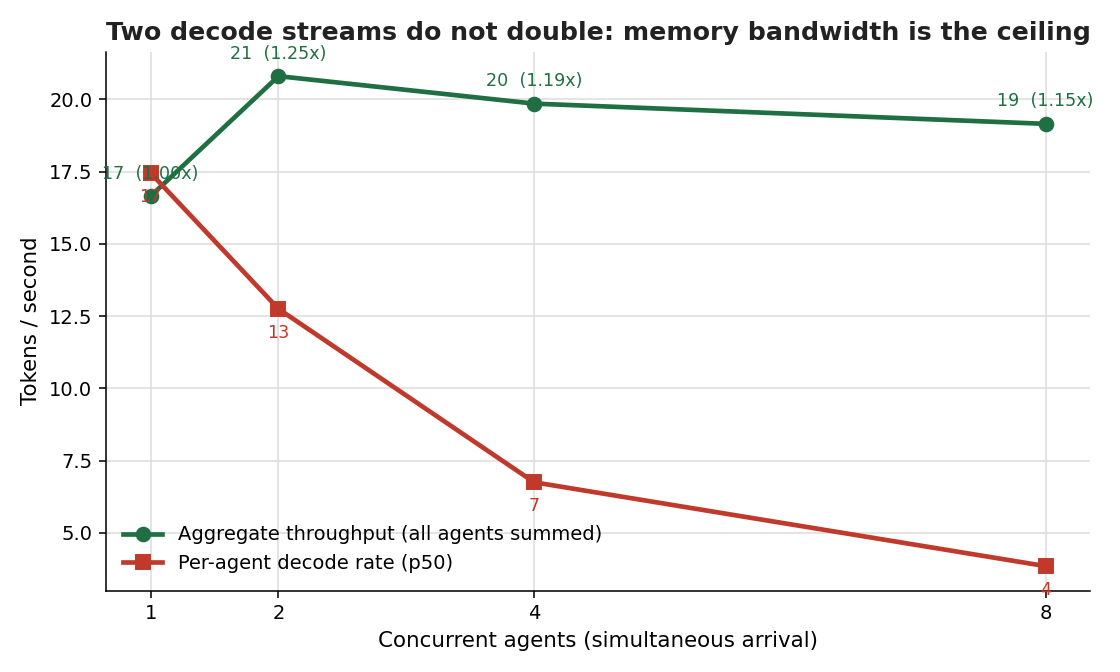
A line chart showing aggregate throughput flattening while per-agent decode rate collapses as concurrent agents rise from one to eight on one local MLX model

You Asked, So I Measured: What Concurrency Actually Costs On One Local Model

Over last week and these last 2 days in this week I posted measured answers to readers both in Twitter and Reddit who asked whether my experiments of 2 local agents on 1 Mac run in parallel or take turns. The answers was that they share one continuous batch, batching is real, and 3 quiet choices collapse it. I thought that was the end of it. It was not. The comments were better than my post, WHICH IS AWESOME, becaue this is the crowdsourcing of brain power I love. I not trying to be a KNOW IT ALL Im trying to be a LEARN IT ALL! ...
August 18, 2026 · 14 min · Fabian Williams
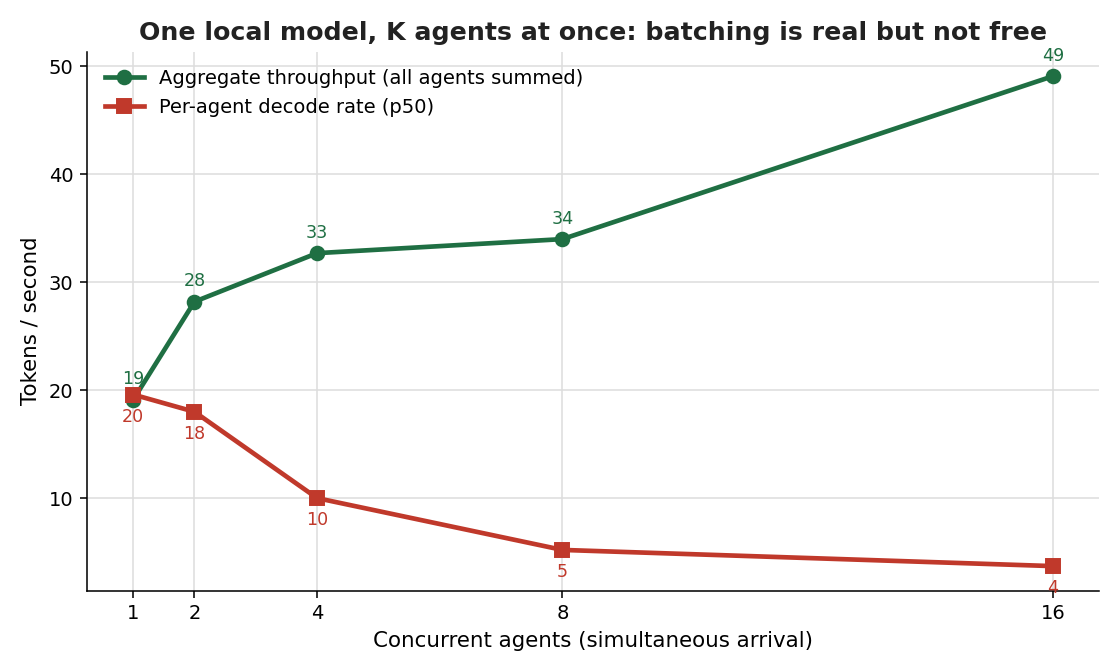
A line chart showing aggregate throughput rising with concurrent agents while per-agent decode rate falls, on one local MLX model

Two Agents, One Local Model: Do They Run in Parallel, or Take Turns? I Measured It.

A reader on Reddit asked me a sharp question about my last post. I had trialed a second local coding agent, Hermes, pointed at the same local Qwen 3.8 model my other agent already uses. His question was simple. Did I ever run both agents at the same time, two separate harnesses hammering one model on one Mac at once. And what about Hermes spawning its own sub-agents against that same endpoint. Is any of that predictable. ...

August 17, 2026 · 9 min · Fabian Williams