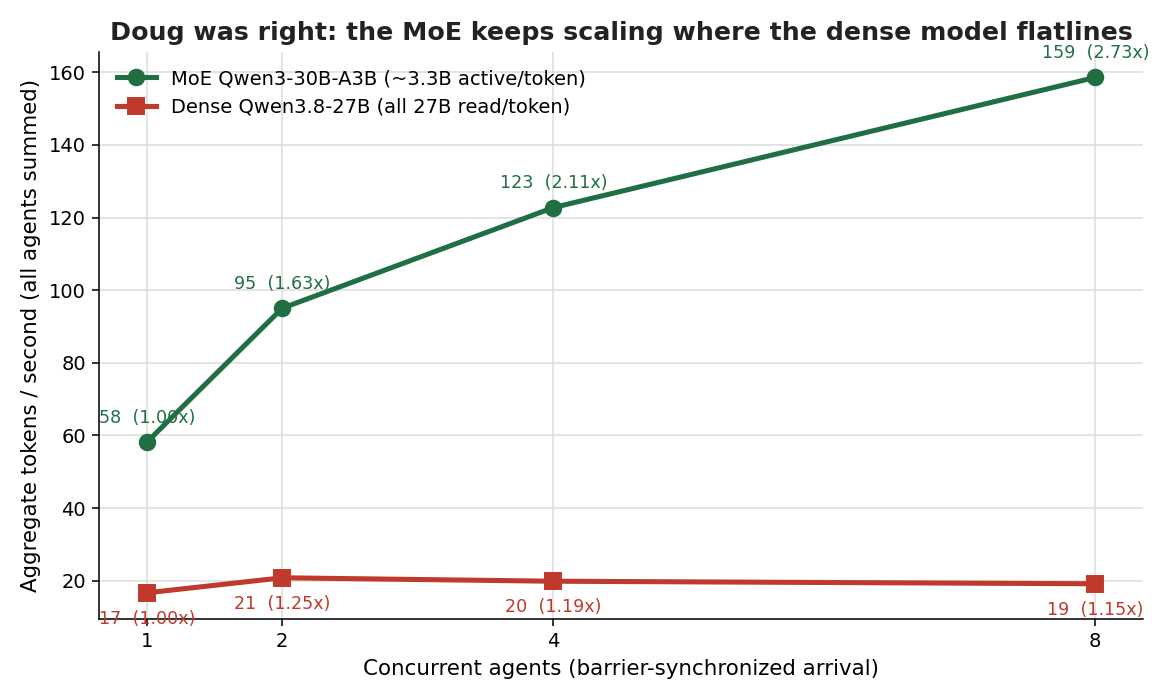
A line chart showing aggregate throughput staying flat near 20 tokens per second on a dense model while a mixture-of-experts model climbs from 58 to 159 tokens per second as concurrent agents rise from one to eight

Doug Was Right: I Swapped In The MoE, And The Concurrency Math Changed

Two days ago I posted 36 barrier-synchronized loads against 1 local model and let the numbers answer a question Reddit handed me. That post ended with a promise. A reader named Doug Ware, who builds applied AI systems for a living, had replied with the one caveat I had not tested, and I said out loud that measuring it was the next thing I would do. This is that measurement. I did not wait, I did not hand-wave it, and I kept every honest asterisk in. ...
August 20, 2026 · 9 min · Fabian Williams
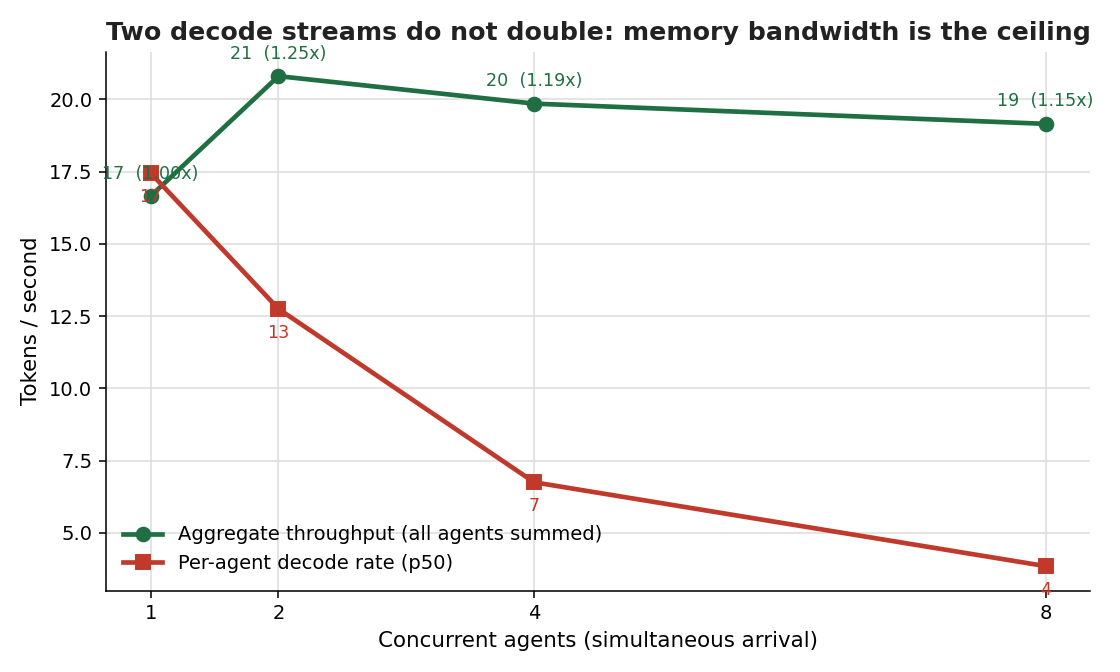
A line chart showing aggregate throughput flattening while per-agent decode rate collapses as concurrent agents rise from one to eight on one local MLX model

You Asked, So I Measured: What Concurrency Actually Costs On One Local Model

Over last week and these last 2 days in this week I posted measured answers to readers both in Twitter and Reddit who asked whether my experiments of 2 local agents on 1 Mac run in parallel or take turns. The answers was that they share one continuous batch, batching is real, and 3 quiet choices collapse it. I thought that was the end of it. It was not. The comments were better than my post, WHICH IS AWESOME, becaue this is the crowdsourcing of brain power I love. I not trying to be a KNOW IT ALL Im trying to be a LEARN IT ALL! ...

August 18, 2026 · 14 min · Fabian Williams