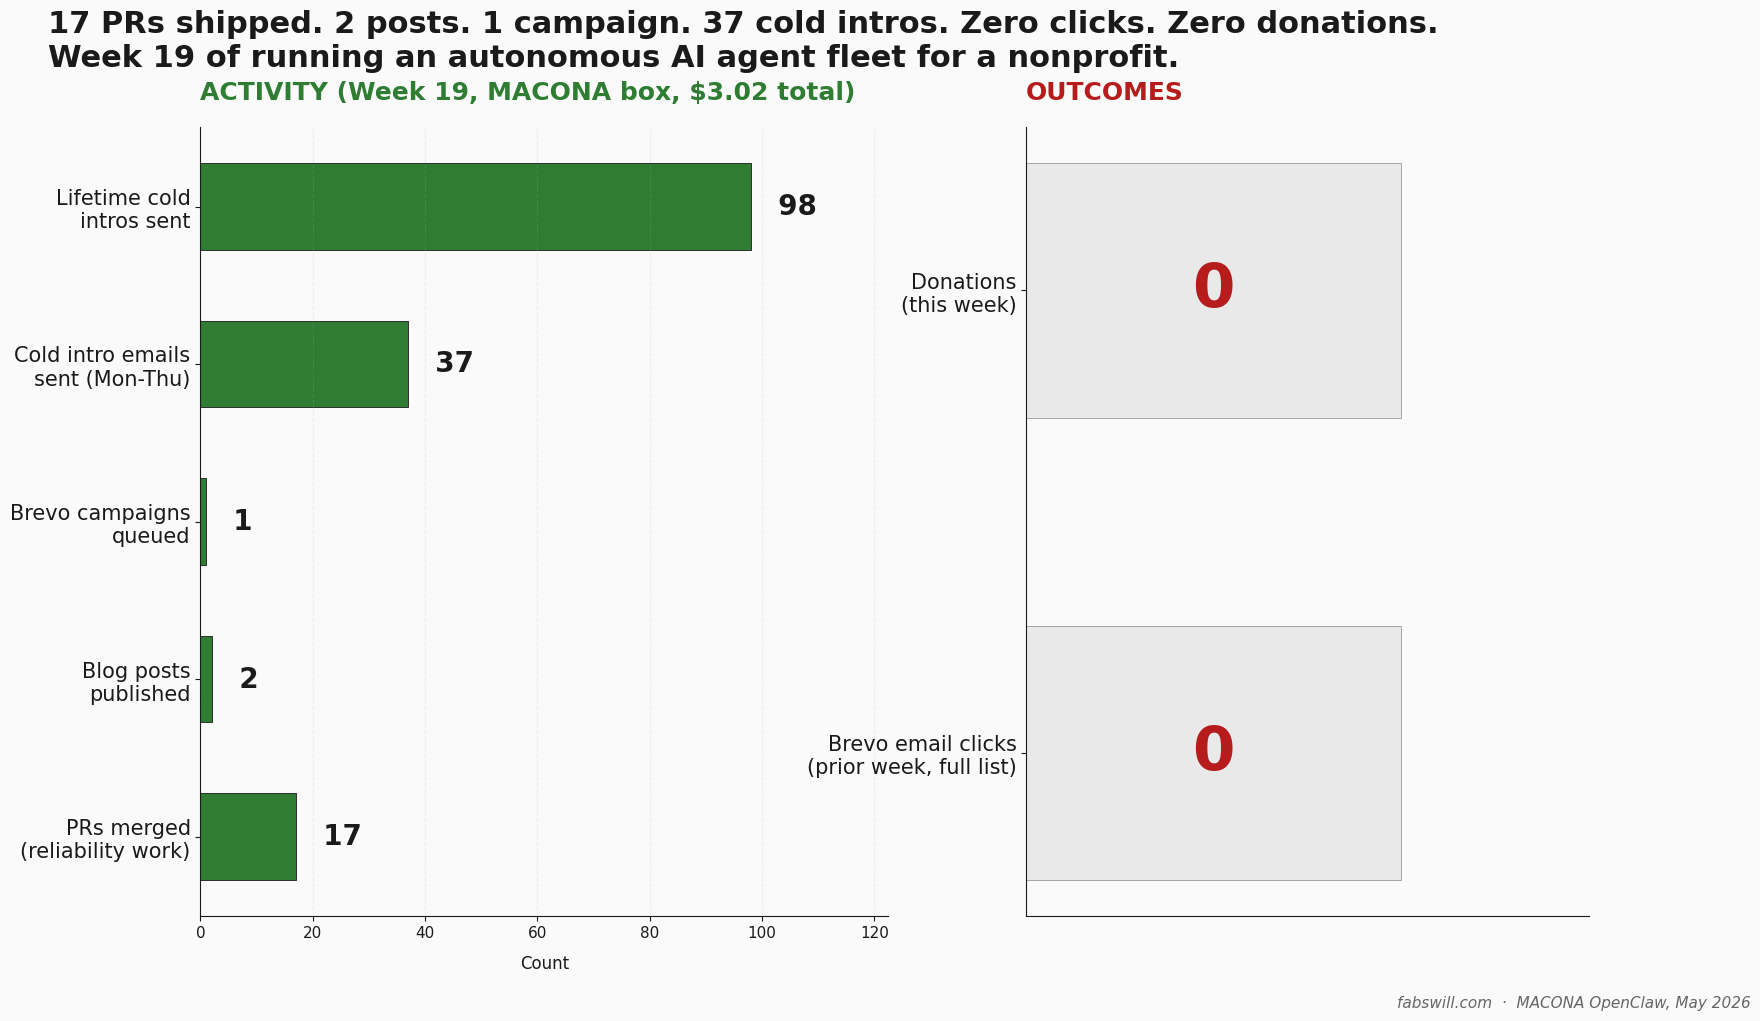
Two-panel chart: left shows 17 PRs, 2 blog posts, 1 campaign, 37 cold intros, 98 lifetime intros shipped in green; right shows zero human clicks and zero donations in red

The AI Agent Fleet Works. The Trust Funnel Does Not.

TL;DR I volunteer with MACONA, a 501(c)(3) nonprofit that ships food, medicine, feminine hygiene products, donated computers, and clothing to communities and schools in West Africa. For a few few monthis now I have run a small autonomous AI agent fleet for the organization: five named agents, cron-driven, running through OpenClaw on a simple Windows box. Week 19 (I track progress via week numbers for me and my Agents) looked like a win on every internal activity metric: 17 reliability PRs merged, 2 awareness-day blog posts published, 1 Brevo campaign queued, and 37 cold introduction emails sent. ...
May 11, 2026 · 14 min · Fabian Williams
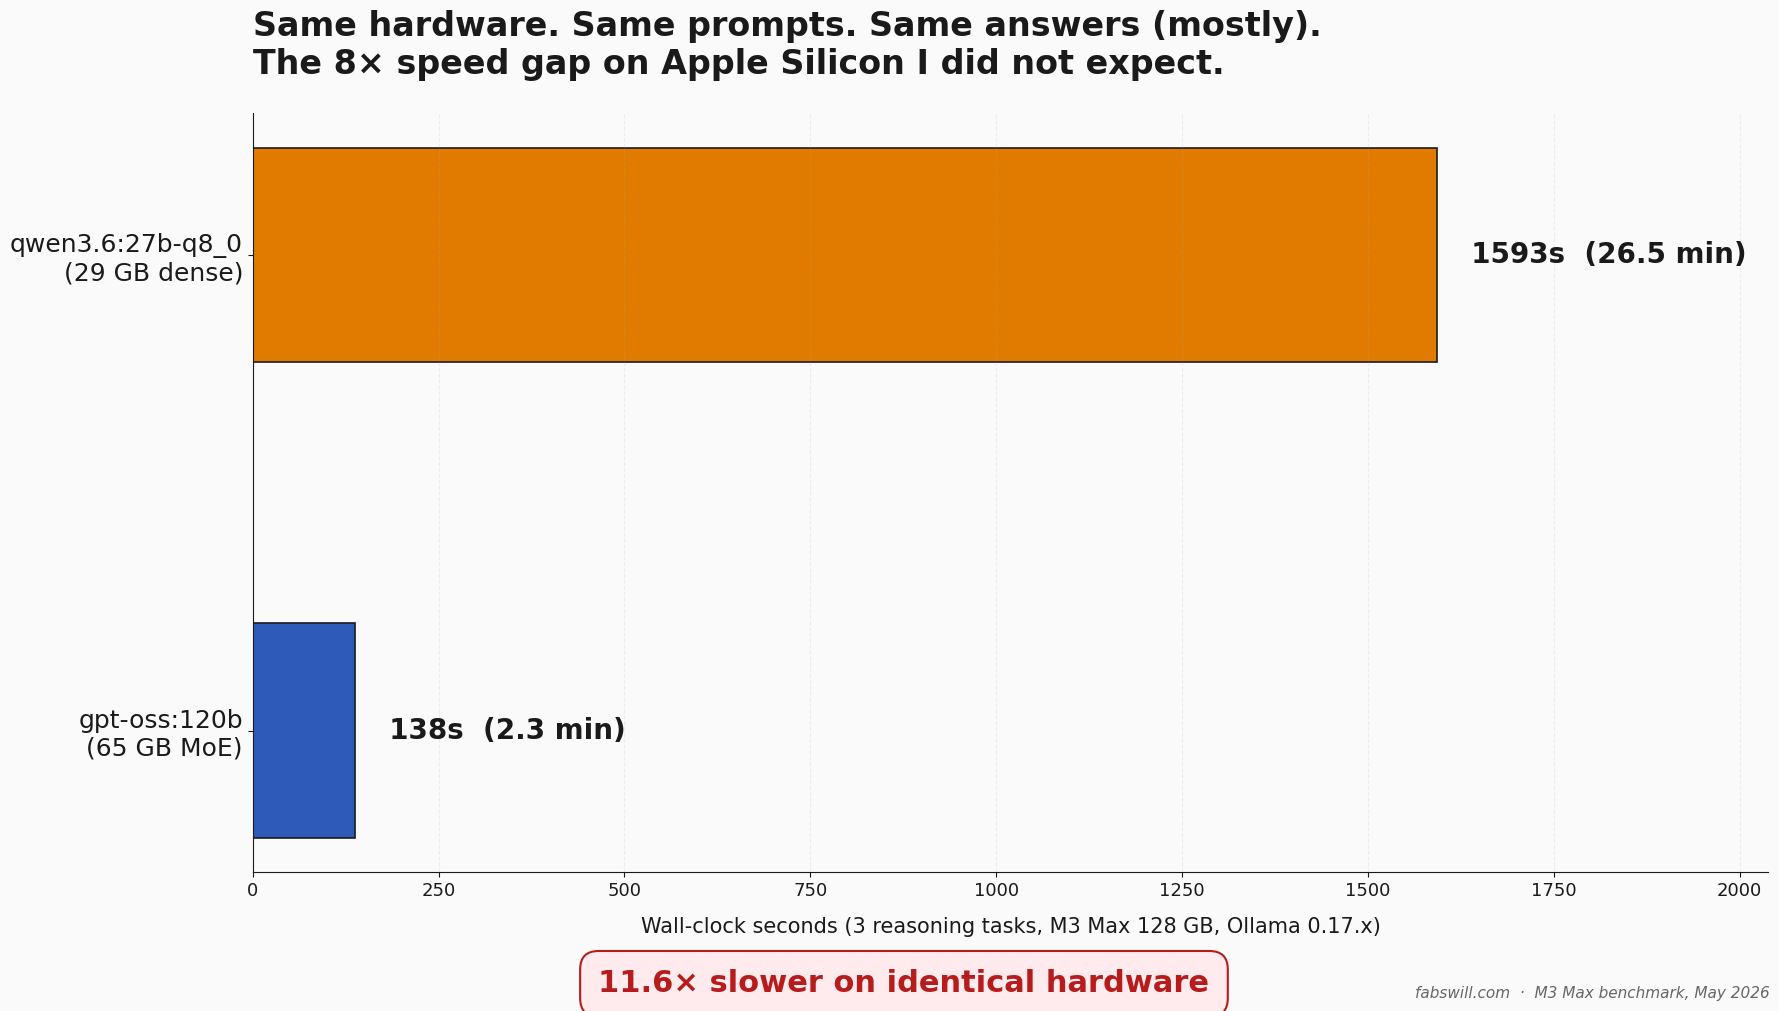
Horizontal bar chart showing gpt-oss:120b at 137 seconds and qwen3.6:27b at 1593 seconds on the same Round 2 reasoning tasks, with an 11.6× slower callout

Qwen 3.6 vs gpt-oss:120b on M3 Max: I Ran a Harder Test, the 8× Speed Gap Surprised Me

TL;DR I published a post last week about replacing gpt-oss:120b with Qwen 3.6 on my MacBook Pro M3 Max. The numbers in that post were real, but one set of tests was structurally gameable — 38 of 40 baseline images were the same class, so an “always-say-A” stub also scored 95 percent. I went back, designed three un-gameable reasoning tasks, and ran them against both local models on identical hardware. gpt-oss:120b finished the three tasks in 137 seconds. qwen3.6:27b-q8_0 took 1593 seconds — 11.6 times slower, on the same M3 Max, for the same prompts and essentially the same answers. This post is the methodology, the receipts, and the honest correction to the migration narrative. ...

May 9, 2026 · 11 min · Fabian Williams